

The Bottom Line
For a decade, the enterprise technology playbook dictated a single strategic imperative: accumulate raw proprietary data to build an unassailable data moat. Enterprise valuations were inextricably linked to the petabytes of information resting in corporate data lakes. In 2026, the physics of that valuation model have inverted. Static data lakes, amassed during the early generative AI boom, are rapidly deteriorating into toxic balance-sheet liabilities.
The market has crossed a critical threshold where the volume of data no longer correlates with competitive defensibility. Instead, unvetted data ingestion directly correlates with regulatory exposure and catastrophic model decay. A recent analysis of over 900,000 public webpages revealed a staggering 74.2% contamination rate of AI-generated synthetic content. The open web is effectively poisoned, and corporate RAG (Retrieval-Augmented Generation) pipelines are ingesting this pollution at scale. We are witnessing the highest-stakes capital reallocation of the decade, moving away from static data hoarding toward real-time, closed-loop telemetry.
The Structural Shift
The erosion of the data moat is driven by a phenomenon researchers classify as Model Autophagous Disorder (MAD), a structural failure mechanism triggered by recursive synthetic data loops. When Large Language Models (LLMs) scrape the web for training, they are now predominantly ingesting outputs generated by previous iterations of LLMs.
Between May 2024 and July 2025, the density of AI-written content in Google’s top-20 search results expanded from 11.11% to 19.56%, climbing at a velocity of 0.6 percentage points per month. By mid-2026, the tech industry hit the theoretical limits of high-quality, human-generated public text, forcing absolute reliance on these recursive synthetic pipelines.
More Read
The mathematical reality of this shift is devastating. Recursive fine-tuning on unverified, machine-generated data causes catastrophic model collapse. Original data distribution tails—the low-probability edge cases that represent true intelligence and nuanced reasoning—are erased. By Generation 9, models suffer complete degradation, outputting entirely meaningless semantic noise. This synthetic training degrades proprietary AI models at an alarming rate, forcing enterprise architects to rethink their foundational dependencies.
The Contrarian Thesis
The prevailing market consensus assumes that cleaning and filtering data is merely an operational overhead. The reality is far more severe: your legacy data lake is a ticking regulatory bomb.
We must re-underwrite enterprise data using a new metric: the Data Storage Liability Ratio. Storing terabytes of unverified, historically scraped data no longer grants asymmetric advantage; it guarantees legal exposure. In early 2026, the Bartz v. Anthropic framework established a $1.5 billion settlement precedent for unvetted dataset scraping.
Furthermore, global regulatory frameworks have pivoted from theoretical guidelines to enforceable mandates. As of August 2, 2026, the EU AI Act’s Article 50 demands granular public summaries and verified provenance for all training data. Concurrently, India’s Digital Personal Data Protection Act (DPDPA) enforces massive financial penalties for holding non-compliant enterprise data stores, fundamentally altering the unit economics of data retention in South Asian markets. Consequently, enterprises hoarding scraped repositories face escalating legal liability and autonomous fraud risks. The asset has become the liability.
First-Principles Analysis: The Physics of Decay
To understand why data moats fail, we must analyze the mechanics of Information Entropy and Embedding Drift.
1. The Entropy Loss Equation:
When an AI model generates data to train its successor, it mathematically samples from the high-density regions of its probability distribution. This results in $H(X_{t+1}) < H(X_t)$, meaning the information entropy decreases with every synthetic generation. The system collapses inward, losing vocabulary diversity, domain-specific edge cases, and cultural nuance.
2. RAG Context Contamination:
Modern enterprises rely heavily on Retrieval-Augmented Generation to ground AI models in corporate reality. However, when legacy internal documents—drafted via AI assistants in 2024—are vectorized and embedded into RAG databases, they create context contamination. The vector embeddings undergo structural embedding drift, skewing the mathematical distance between concepts and causing the model to hallucinate proprietary facts based on synthetic noise.
3. The “Replace vs. Accumulate” Theorem:
Model collapse is triggered by data replacement ($D_{t+1} = D_{\text{synthetic}}$), not just the presence of synthetic data. Survival requires a strict Accumulation Strategy ($D_{t+1} = D_{\text{human}} \cup D_{\text{verified\_synthetic}}$), mandating high-fidelity human telemetry to anchor the statistical variance.
Reality Check: The Data Defensibility Matrix
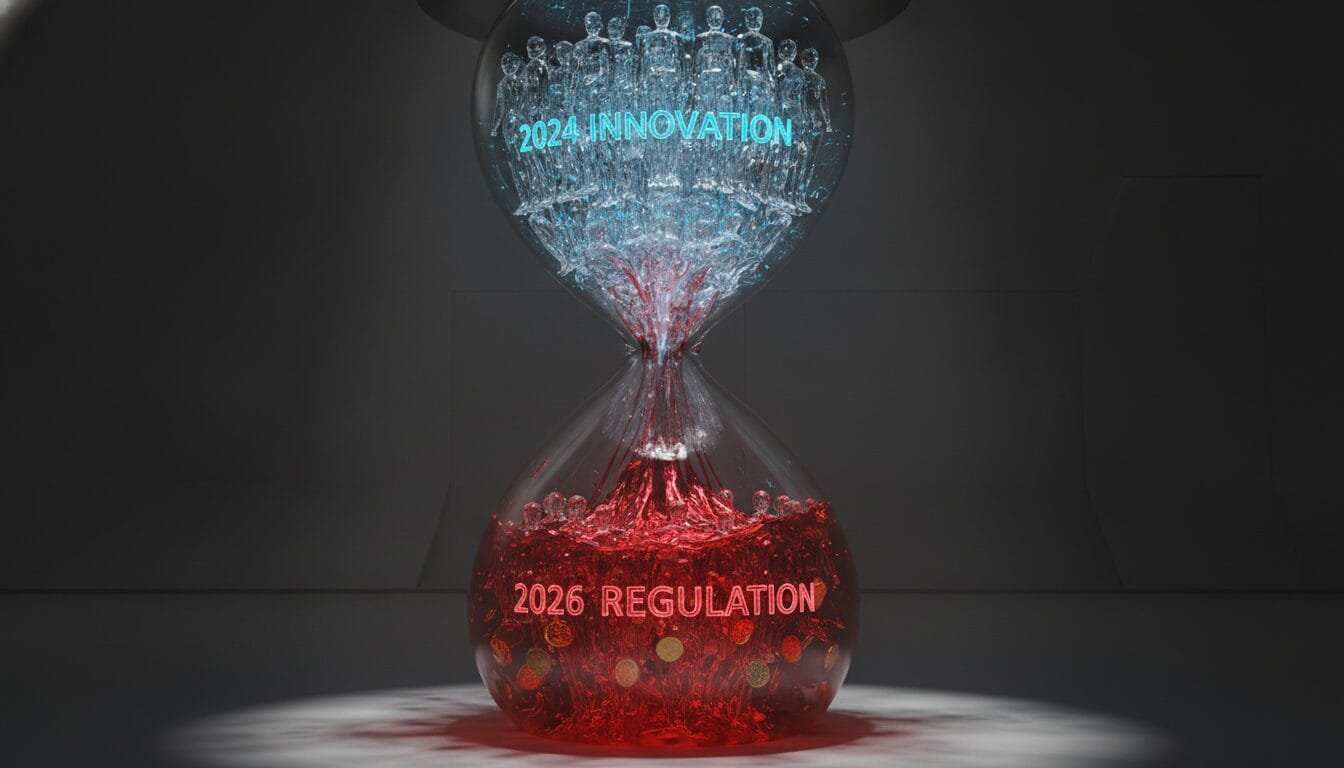
To map the delta between institutional narrative and technical reality, observe the rapid depreciation of conventional enterprise assets.
| Strategic Asset | The 2024 Hype | The 2026 Execution Reality |
|---|---|---|
| Historical Text Archives | Unassailable knowledge moat. | Toxic liability subject to Article 50 deletion mandates. |
| Web-Scraped Datasets | Cheap fuel for continuous LLM fine-tuning. | Triggers Generation 9 catastrophic model collapse. |
| Synthetic Data Augmentation | Infinite, cost-free training data generation. | Requires massive capital expenditure for human verification telemetry. |
| Static RAG Vector Stores | Enterprise-grade accuracy and factual grounding. | Suffers from severe Embedding Drift and context contamination. |
Practical Implementation: The Action Telemetry Pivot
If static data is toxic, competitive advantage now resides in Closed-Loop Action Data. The unit of value in 2026 is no longer the documented text; it is the human correction of the machine’s output.
To survive the Data Half-Life Metric—the speed at which static knowledge becomes statistically irrelevant—enterprises must pivot from storage to workflow orchestration. As automated workflows shift capital to AI agents, companies must instrument every software touchpoint to capture human verification. When an expert rejects an AI-generated contract clause, edits a line of code, or overrides a supply chain prediction, that specific delta—the human override—is the only entropy-rich data left in the ecosystem.
Engineering teams must immediately audit their RAG vector databases. Implement aggressive cryptographic hashing and provenance watermarking to identify which embeddings were natively generated by humans versus those synthesized by internal AI tools. Purge the synthetic recursion loops.
Actionable Scenarios
To align capital deployment with 2026 structural realities, CXOs must operate within the following framework.
| Strategic Posture | Actionable Scenario (Execute Immediately) | Avoid Scenario (Divest & Purge) |
|---|---|---|
| Data Acquisition | Acquire SaaS platforms solely to harvest real-time user-agent interaction telemetry and human override signals. | Purchasing static third-party datasets or historical web-scraping archives to boost foundational model size. |
| Infrastructure Spend | Reallocate cloud budget toward cryptographic data provenance tracing and rigorous embedding validation engines. | Expanding cold-storage data lakes for unstructured, unverified corporate documents and legacy media. |
| Regulatory Compliance | Implement automated “Machine Unlearning” pipelines to dynamically purge copyrighted or DPDPA-violating data. | Relying on opaque “black box” foundation models that cannot provide Article 50-compliant data lineage reports. |
The Sovereign Playbook
The 2030 horizon requires a fundamental unlearning of Silicon Valley’s foundational myth: that hoarding the past controls the future. The physical constraints of intelligence generation have exposed the fragility of passive accumulation. True cognitive authority in the next decade belongs to sovereign actors and institutional giants who recognize that the new moat is structural workflow integration, not archival mass.
The Sovereign Playbook demands transitioning from a “Data Landlord” to a “Telemetry Gatekeeper.” Capital allocation must aggressively pivot toward human-in-the-loop interfaces. You do not build leverage by owning the textbook; you build leverage by owning the specific moment a human expert corrects the machine’s interpretation of that textbook. This requires establishing strict gatekeepers of enterprise AI who govern data ingestion with the same rigorous protocols as financial auditing.
As synthetic degradation accelerates, the open web will become a sprawling wasteland of recursive noise. Information asymmetry will heavily favor enterprises that can verify the origin of a single data point over those possessing petabytes of unverified entropy. To secure a multi-decade asymmetric advantage, liquidate your static data liabilities. Invest ruthlessly in dynamic, closed-loop validation systems. In an era where machine intelligence is a commoditized utility, verified human friction is the only asset that scales.