

The Signal Check
Within the intelligence operations of the News Desk, our mandate is absolute: separate structural reality from market noise. For two decades, NVIDIA operated not as a silicon vendor, but as a tollbooth on compute. Their Compute Unified Device Architecture (CUDA) formed an impregnable software moat, historically capturing up to ~92% of the AI data center market. But as global AI spending accelerates toward a staggering $2.59 trillion by 2026—with infrastructure consuming over 45% of that capital—C-suites are desperate for margin relief.
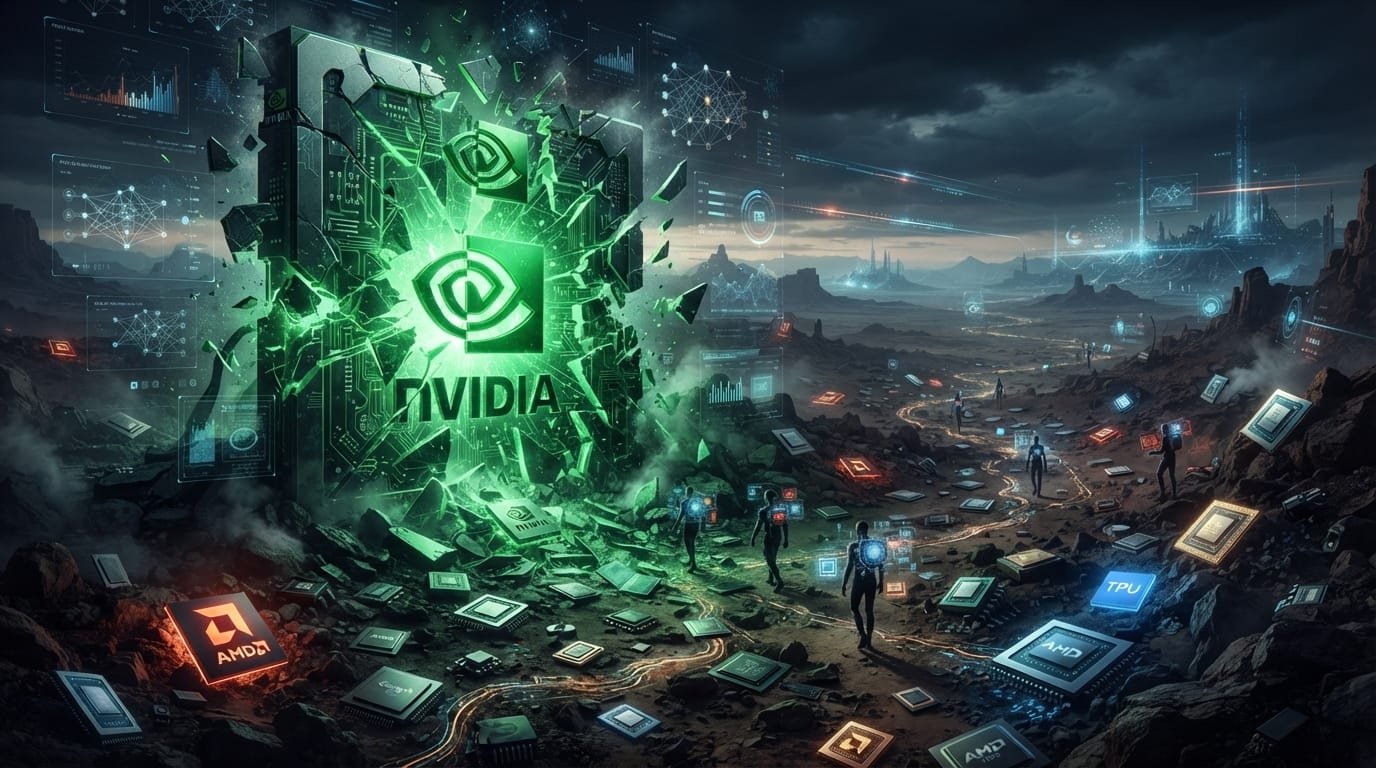
NVIDIA’s monopoly isn’t fracturing because someone built a superior general-purpose chip. It is breaking because the software layer is actively abstracting the hardware into irrelevance.
For media conglomerates and enterprise intelligence units, this hardware shift fundamentally alters capital allocation. Underlying compute costs dictate which automated financial synthesis engines, real-time verification models, and AI-driven reporting tools survive. If silicon is no longer monopolized, deployment velocity scales exponentially. The operational bottleneck shifts entirely to software orchestration.
The Structural Shift
Decoupling AI frameworks from hardware changes the foundation of enterprise infrastructure. Open abstractions like PyTorch 2.x, OpenAI Triton, vLLM, and the Unified Acceleration (UXL) Foundation dynamically compile intermediate representations (MLIR) down to vendor-specific machine code. They provide a unified front-end while treating the silicon below as a commoditized backend. This establishes a new class of abstraction gatekeepers.
This hardware-agnostic momentum dictates capital allocation at the highest levels. Meta is running over 173,000 AMD Instinct MI300X units, a deployment that pushed AMD’s data center GPU revenue to $4.3 billion in Q3 2025 alone. Simultaneously, Google and Meta’s “TorchTPU” initiative re-engineered the Google TPU stack to run PyTorch natively. By replacing rigid JAX/XLA defaults with seamless PyTorch foundation evolution capabilities, they executed zero-code-change migrations across massive multimodal workloads.
Yet physical realities fiercely resist purely software-defined solutions. The raw thermal output of clustered heterogeneous accelerators is shifting the primary constraint from silicon to power capacity. Hyperscalers are now competing directly with public utility loads just to keep data centers online.
Execution Reality vs. Market Hype
| Market Hype (The Noise) | Technical Execution (The Signal) |
|---|---|
| Open-source engines instantly eliminate CUDA vendor lock-in. | Raw framework support exists, but achieving high-performance multi-backend kernel orchestration demands massive bespoke engineering. |
| Alternative silicon provides a flat 30-40% CapEx reduction. | CapEx savings are routinely cannibalized by a “Developer Productivity Tax” paid in compiler instability and runtime bugs. |
| Enterprise AI is constrained solely by GPU availability. | Inference is memory-bandwidth bound, forcing next-generation thermal architectural shifts and strict ASIC prioritization. |
The Contrarian Thesis
Consensus assumes that breaking NVIDIA’s software tax automatically liberates enterprise margins. The data proves otherwise. Removing the CUDA tollbooth dumps Chief Information Officers directly into a hardware Wild West.
Organizations chasing a 30% discount on alternative compute clusters routinely watch those savings evaporate. The culprit is the hidden Developer Productivity Tax. Attempting to run production inference on fragmented, unproven stacks forces high-priced engineering teams to debug obscure compiler errors rather than shipping features. Silicon is commoditizing, but elite engineering hours are not. The monopoly isn’t vanishing—it is simply migrating up the stack.